Data Source Guides#
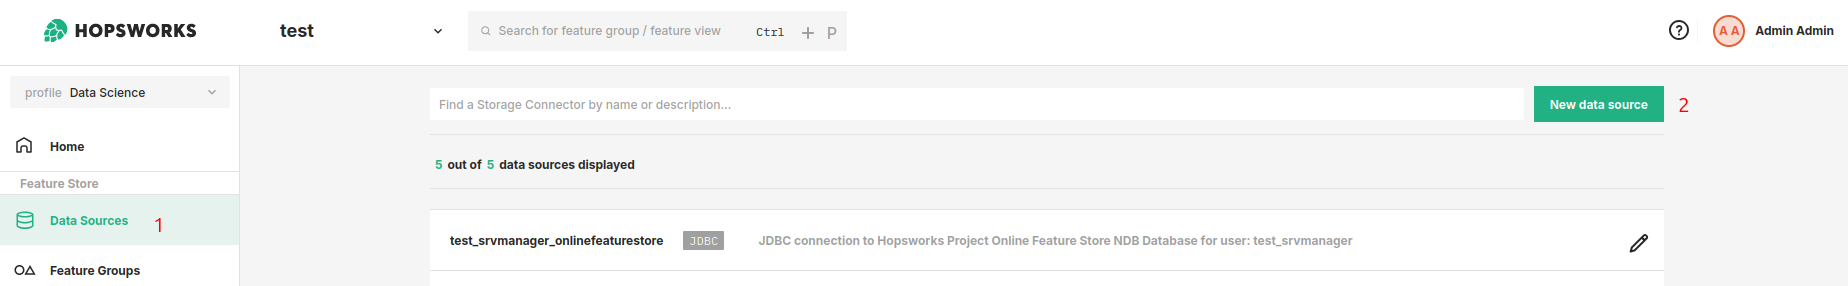
You can define data sources in Hopsworks for batch and streaming data sources. Data Sources securely store the authentication information about how to connect to an external data store. They can be used from programs within Hopsworks or externally.
Warning
In the previous versions of Hopsworks, this used to be called a storage connector.
There are four main use cases for Data Sources:
- Simply use it to read data from the storage into a dataframe.
- External (on-demand) Feature Groups can be defined with data sources. This way, Hopsworks stores only the metadata about the features, but does not keep a copy of the data itself. This is also called the Connector API.
- Write training data to an external storage system to make it accessible by third parties.
- Managed feature group that stores offline data in an external storage system. Currently S3, GCS and AWS Glue connectors are supported.
Data Sources provide two main mechanisms for authentication: using credentials or an authentication role (IAM Role on AWS or Managed Identity on Azure). Hopsworks supports both a single IAM role (AWS) or Managed Identity (Azure) for the whole Hopsworks cluster or multiple IAM roles (AWS) or Managed Identities (Azure) that can only be assumed by users with a specific role in a specific project.
By default, each project is created with three default Data Sources: A JDBC connector to the online feature store, a HopsFS connector to the Training Datasets directory of the project and a JDBC connector to the offline feature store.
Cloud Agnostic#
Cloud agnostic storage systems:
-
Snowflake
Query Snowflake databases and tables using SQL.
-
Kafka
Read from a Kafka cluster into a Spark Structured Streaming Dataframe.
-
SAP HANA
Query SAP HANA tenant databases using SQL.
-
JDBC
Connect to any JDBC compatible database and query it using SQL.
-
REST API
Connect to external HTTP APIs with configurable headers and authentication.
-
CRM, Sales & Analytics
Connect to supported CRM, sales, and analytics platforms.
-
HopsFS
Connect and read from directories of Hopsworks' internal file system.
AWS#
For AWS the following storage systems are supported:
-
S3
Read file-based storage in S3 such as parquet or CSV.
-
AWS Glue
Integrate with the Glue Data Catalog over S3, for Iceberg, Delta, Hudi and plain files.
-
Redshift
Query Redshift databases and tables using SQL.
-
RDS (SQL)
Query the Amazon Relational Database Service using SQL.
Azure#
For Azure the following storage systems are supported:
-
ADLS
Read file-based storage in ADLS such as parquet or CSV.
GCP#
For GCP the following storage systems are supported:
Databricks (AWS only)#
For Databricks on AWS the following storage systems are supported:
-
Unity Catalog
Browse catalogs, schemas, and Delta tables, and mount them as external feature groups.
Databricks on Azure and Databricks on GCP are not supported yet. See the Unity Catalog guide for the specific reasons and the status of follow-up work.
Next Steps#
Move on to the Configuration and Creation Guides to learn how to set up a data source.