How-To set up a Hopsworks Data Source#
Introduction#
A Hopsworks Data Source connects to a project on another Hopsworks cluster. Its databases are the feature stores that the remote project can read, and its tables are their feature groups.
Once configured, you can use a remote feature group as the basis for an external (on-demand) Feature Group, read through the remote cluster's Hopsworks Query Service, or copy it into a managed Feature Group of this cluster with a dltHub ingestion job.
Prerequisites#
Before you begin this guide you'll need the following from the remote Hopsworks cluster:
- Host: The host name or IP address of the remote cluster, the one in the address of its user interface, without
https://or a path. The remote cluster must answer at this address: a redirect to another address is refused. - Port: The HTTPS port of the remote cluster. The default is
443. - Project: The name of the project on the remote cluster to read from.
- API key: An API key of a member of that project, created on the remote cluster under
Account Settings>API keys. The key needs thePROJECTandFEATURESTOREscopes. The data source reads what the key's user can read: the project's own feature store and the feature stores shared with the project.
The remote cluster must have its Hopsworks Query Service enabled, and the Hopsworks Query Service must be reachable from this cluster. This cluster reads the remote cluster's loadbalancer_external_domain_feature_query variable to find it, and connects to it on port 5005. When the variable is not set, it connects to the host of the data source on port 5005.
Creation in the UI#
Step 1: Set up new Data Source#
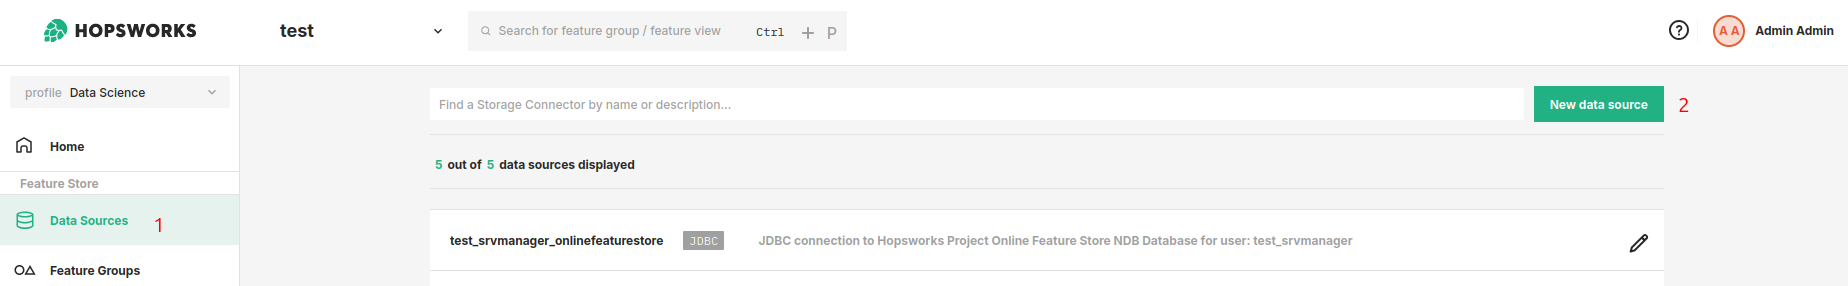
Head to the Data Sources view on Hopsworks and click New data source. The Add a data source catalog opens below. Pick the Hopsworks card to open the creation form.
Step 2: Enter the remote cluster#
Enter the details for the remote cluster. Start by giving the data source a name and an optional description.
- Enter the Host of the remote cluster.
- Enter the Port, or leave it empty for
443. - Enter the name of the remote Project.
- Enter the API key.
- Leave Verify the server certificate and hostname checked, unless the remote cluster uses a self-signed certificate. The setting applies to the REST calls to the remote cluster. The connection to its Hopsworks Query Service always verifies the remote cluster's certificate against the remote project's certificate authority.
- Click on "Save Credentials".
Creation with the CLI#
hops datasource create hopsworks remote_sales --host hopsworks.example.com --project sales --api-key - < key.txt
Add --no-tls-verify for a remote cluster with a self-signed certificate.
Browse the remote feature groups#
The data source lists the remote feature stores as databases, and their feature groups as tables named <name>_<version>. Spine groups are not listed, since they hold no data.
import hopsworks


project = hopsworks.login()
fs = project.get_feature_store()

ds = fs.get_data_source("remote_sales")
ds.get_databases()
# ['sales_featurestore', 'shared_featurestore']
[t.table for t in ds.get_tables("sales_featurestore")]
# ['transactions_1', 'transactions_2']
Mount a remote feature group#
An external feature group on a Hopsworks data source reads one remote feature group. It takes no SQL query, and Hopsworks cannot create a Trino catalog from this data source.
import hopsworks


project = hopsworks.login()
fs = project.get_feature_store()

ds = fs.get_data_source("remote_sales")
tables = ds.get_tables("sales_featurestore")
table = next(t for t in tables if t.table == "transactions_2")
data = table.get_data()

fg = fs.create_external_feature_group(
    name="remote_transactions",
    version=1,
    data_source=table,
    features=data.features,
    primary_key=["id"],
    statistics_config=False,
)
fg.save()
df = fg.read()
A read sends the remote cluster a query for the selected features of the remote feature group. The row limit of a preview or of fg.read(limit=...) is sent with it when the query only selects features of this one feature group: with a filter, join, aggregate or ordering the limit would change the result, so it is applied on this cluster after the read. Filters are applied on this cluster after the read, so a filtered read transfers the whole feature group. A read is refused once the remote rows that this cluster's Hopsworks Query Service holds for all running queries pass 2 GiB, since it keeps them in memory to run the queries; read a large feature group with a limit, or copy it with an ingestion job. Reads use the Python engine. Spark cannot read an external feature group on a Hopsworks data source, so create it with statistics_config=False: statistics are computed by a Spark job.
Use it as an ingestion source#
The data source can also be used with the dltHub-based ingestion workflow described in Ingest Data with dltHub, to copy a remote feature group into a managed feature group of this cluster. The ingestion job supports full loads and incremental loads. For an incremental load, the remote query only returns rows whose cursor column is at least the last value the previous run loaded.