How to create an External Feature Group#
Introduction#
In this guide you will learn how to create and register an external feature group with Hopsworks. This guide covers creating an external feature group using the Hopsworks APIs as well as the user interface.
Prerequisites#
Before you begin this guide we suggest you read the External Feature Group concept page to understand what a feature group is and how it fits in the ML pipeline.
Create using the Hopsworks APIs#
Retrieve the Data Source#
To create an external feature group using the Hopsworks APIs you need to provide an existing data source.
Create an External Feature Group#
The first step is to instantiate the metadata through the create_external_feature_group method. Once you have defined the metadata, you can persist the metadata and create the feature group in Hopsworks by calling fg.save().
SQL based external feature group#
query = """
    SELECT TO_NUMERIC(ss_store_sk) AS ss_store_sk
        , AVG(ss_net_profit) AS avg_ss_net_profit
        , SUM(ss_net_profit) AS total_ss_net_profit
        , AVG(ss_list_price) AS avg_ss_list_price
        , AVG(ss_coupon_amt) AS avg_ss_coupon_amt
        , sale_date
        , ss_store_sk
    FROM STORE_SALES
    GROUP BY ss_store_sk, sales_date
"""

fg = feature_store.create_external_feature_group(
    name="sales",
    version=1,
    description="Physical shop sales features",
    query=query,
    data_source=ds,
    primary_key=["ss_store_sk"],
    event_time="sale_date",
)

fg.save()
Data Lake based external feature group#
You can read the full FeatureStore.create_external_feature_group documentation for more details. name is a mandatory parameter of the create_external_feature_group and represents the name of the feature group.
The version number is optional, if you don't specify the version number the APIs will create a new version by default with a version number equals to the highest existing version number plus one.
If the data source is defined for a data warehouse (e.g., JDBC, Snowflake, Redshift) you need to provide a SQL statement that will be executed to compute the features. If the data source is defined for a data lake, the location of the data as well as the format need to be provided.
Additionally we specify which columns of the DataFrame will be used as primary key, and event time. Composite primary keys are also supported.
Register the metadata#
In the snippet above it's important that the created metadata object gets registered in Hopsworks. To do so, you should invoke the save method:
Enable online storage#
You can enable online storage for external feature groups, however, the sync from the external storage to Hopsworks online storage is not automatic and needs to be setup manually. For an external feature group to be available online, during the creation of the feature group, the online_enabled option needs to be set to True.
external_fg = fs.create_external_feature_group(
    name="sales",
    version=1,
    description="Physical shop sales features",
    query=query,
    data_source=ds,
    primary_key=["ss_store_sk"],
    event_time="sale_date",
    online_enabled=True,
)
external_fg.save()

# read from external storage and filter data to sync to online
df = external_fg.read().filter(external_fg.customer_status == "active")

# insert to online storage
external_fg.insert(df)
The insert() method takes a DataFrame as parameter and writes it only to the online feature store. Users can select which subset of the feature group data they want to make available on the online feature store by using the query APIs.
Limitations#
Hopsworks Feature Store does not support time-travel queries on external feature groups.
Additionally, support for .read() and .show() methods when using by the Python engine is limited to external feature groups defined on BigQuery and Snowflake and only through the ArrowFlight Server with DuckDB, which Hopsworks enables by default. Nevertheless, external feature groups defined top of any data source can be used to create a training dataset from a Python environment invoking one of the following methods: FeatureView.create_training_data, FeatureView.create_train_test_split or FeatureView.create_train_validation_test_split.
API reference
Create using the UI#
You can also create a new feature group through the UI. For this, navigate to the Data Sources section and make sure you have a data source for the desired platform, or create a new one. Table browsing is available for database and warehouse sources such as Snowflake, BigQuery, Redshift and SQL databases; the built-in HopsFS and JDBC sources of a project do not offer it.
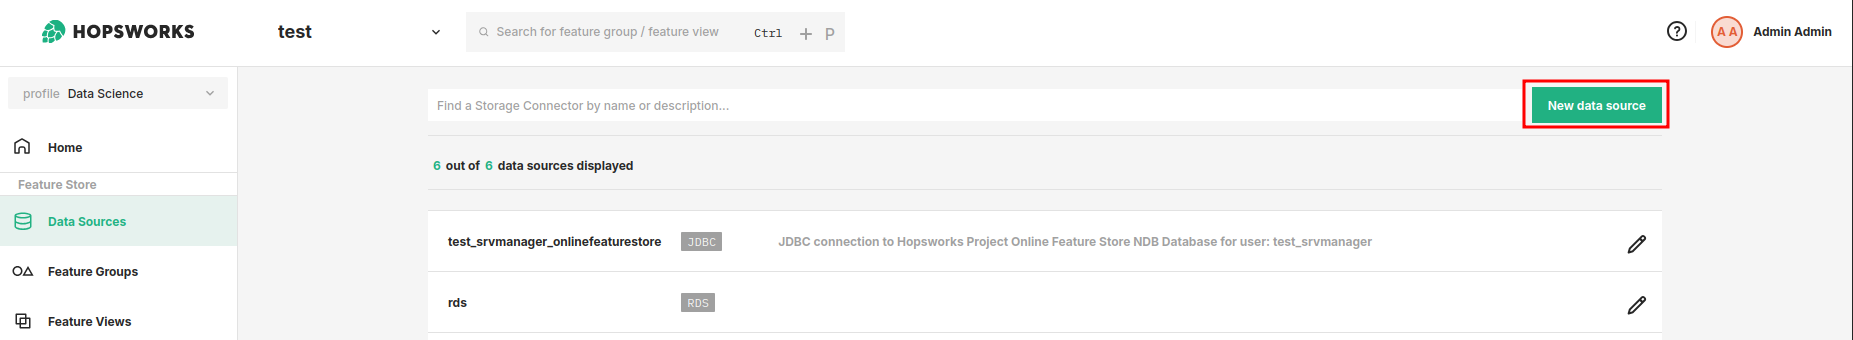
Open the data source with the pencil at the end of its row and click Next: Select Tables at the bottom of the form.
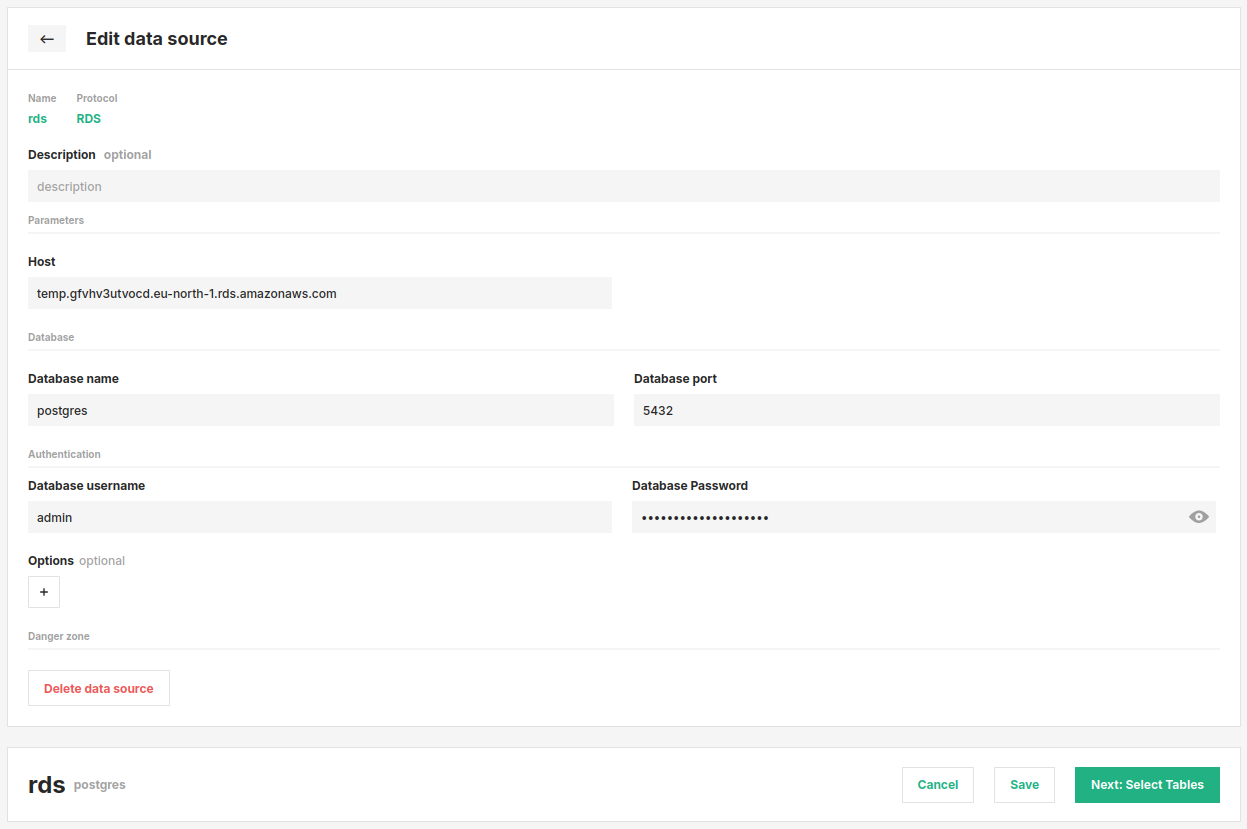
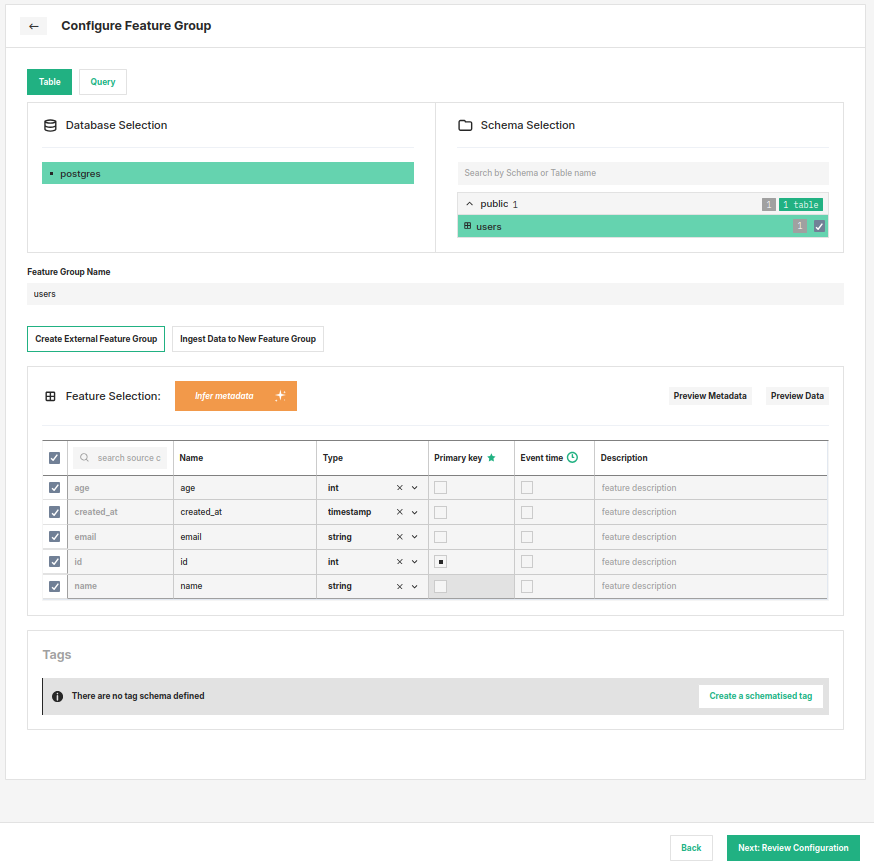
In the UI you can either select one or more tables or define a custom SQL query.
Option A: Select tables#
The database navigation structure depends on your specific data source. You'll navigate through the appropriate hierarchy for your platform, such as Database → Schema → Table for Snowflake, or Project → Dataset → Table for BigQuery.
Select one or more tables. For each selected table, you must designate one or more columns as primary keys before proceeding. You can also optionally select a single column as the event time for the row (supported types are timestamp, date and bigint), and edit names and data types of the individual columns you want to include. Preview Metadata and Preview Data show the source schema and a sample of rows before you commit to anything.
Option B: Define a SQL query#
Instead of selecting a table, you can write a custom SQL query to define the feature group. This is useful when you need to join multiple tables or apply transformations at read time. Click Fetch Schema to resolve the columns of the query, then, as with the table option, designate one or more columns as primary keys, optionally pick an event time column and give the feature group a name.
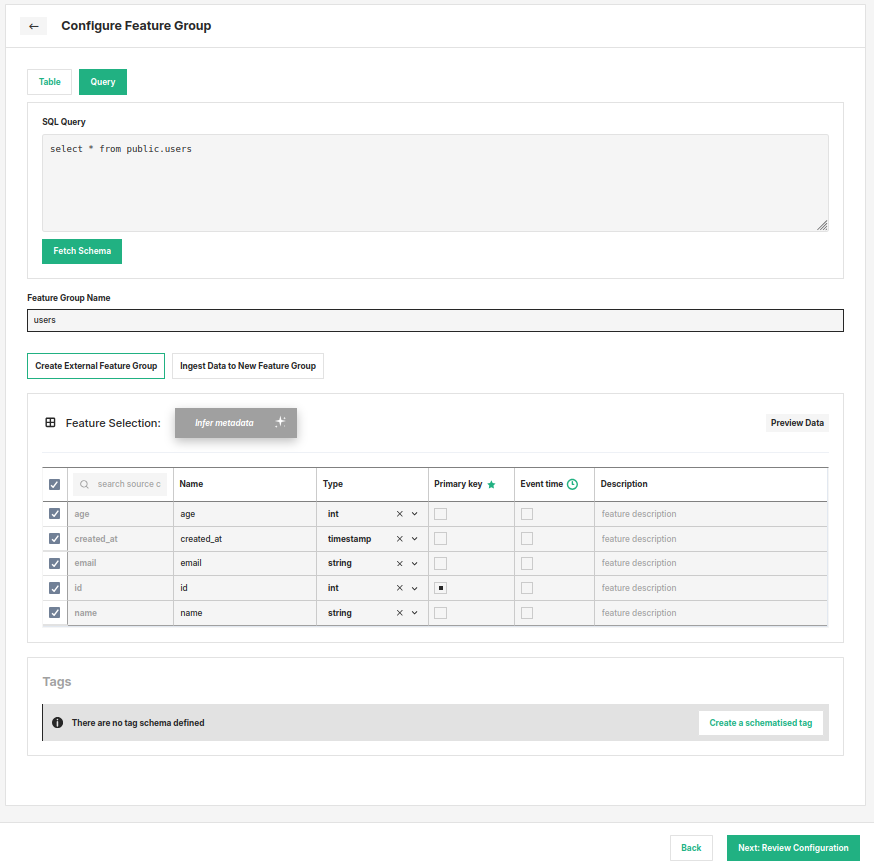
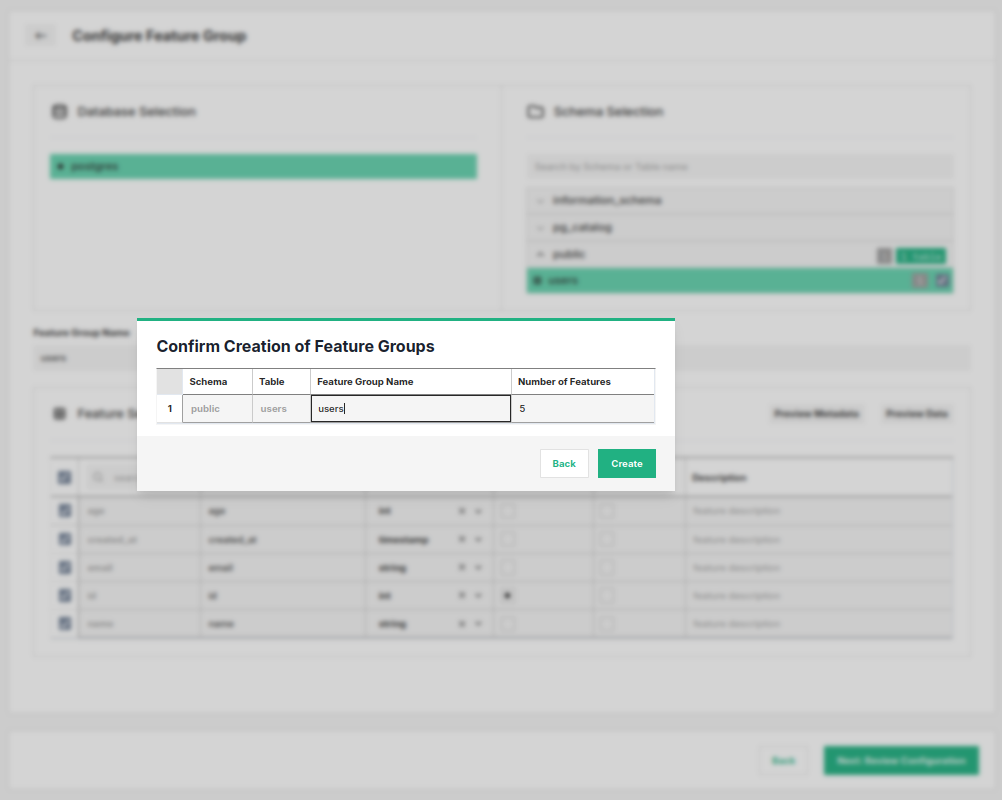
Complete the creation by clicking Next: Review Configuration at the bottom of the page. As the last step, you will be able to rename the feature groups and confirm their creation.
Data Source submenu#
An external feature group has a Data Source entry in its menu, after Overview. The page shows the data source the feature group reads through, which the overview used to show as a Storage Connector panel, and a Test Connection button. Test Connection reads one row of the backing table or query as you and shows the result; it takes up to a minute.
For a data source with provided credentials the page adds a Your access section: your access state, when it was last checked, the message the database returned, My credentials to add or change your own credentials, and Test Connection. The states and what each one means are listed in the data source guide, under access to mounted tables.
Greyed-out feature groups in the catalog#
In the feature group catalog, an external feature group you cannot read with your own credentials is greyed out, with the reason under its name and one button:
| Your state | Reason shown | Button |
|---|---|---|
NO_CREDENTIALS | Add your credentials for data source <name> to use this feature group. | Add my credentials |
INVALID_CREDENTIALS | Your credentials for data source <name> were rejected. | Test Connection |
NO_ACCESS | You don't have privileges to read the backing table <database>.<table> in data source <name>. | Test Connection |
ERROR | Could not check access to data source <name>: <message>. | Test Connection |
While a check is queued (PENDING) the card shows Checking access and keeps its normal look. A greyed-out feature group stays clickable, so its pages and its Data Source submenu remain reachable.
Feature groups from a shared feature store#
Credentials for a provided data source belong to the project that owns the data source. To read a feature group from a feature store shared with your project, add your credentials in the project that owns its data source. In your own project, the Data Source submenu and the greyed-out card point you to the owning project instead of opening the credentials dialog.
From the API and the CLI#
The same state is on the feature group object, and the check can be run from code:
fg = fs.get_feature_group("sales_external", version=1)
fg.data_source_access  # None for a data source with shared credentials

access = fg.test_data_source_access()
if access["status"] != "OK":
    print(access["status"], access["error_code"], access["message"])
hops fg list has an ACCESS column with your state in lower case, and - for every other feature group. hops fg test-access runs the check: