Python Deployment#
Introduction#
Python deployments allow you to deploy a Python script as a service without requiring a model artifact in the Model Registry. This is useful for custom inference pipelines, feature view deployments, or any Python-based program that needs to be served behind an HTTP endpoint.
Incoming requests are directed to port 8080
Python deployments run your script directly on port 8080. Therefore, make sure your implementation listens to 8080 port for handling incoming requests.
gRPC protocol not supported
Use your favourite HTTP server
There are no constraints on the framework or library used: you can use Flask, FastAPI, or any other HTTP server.
In each Python deployment, you can configure the following:
Web UI#
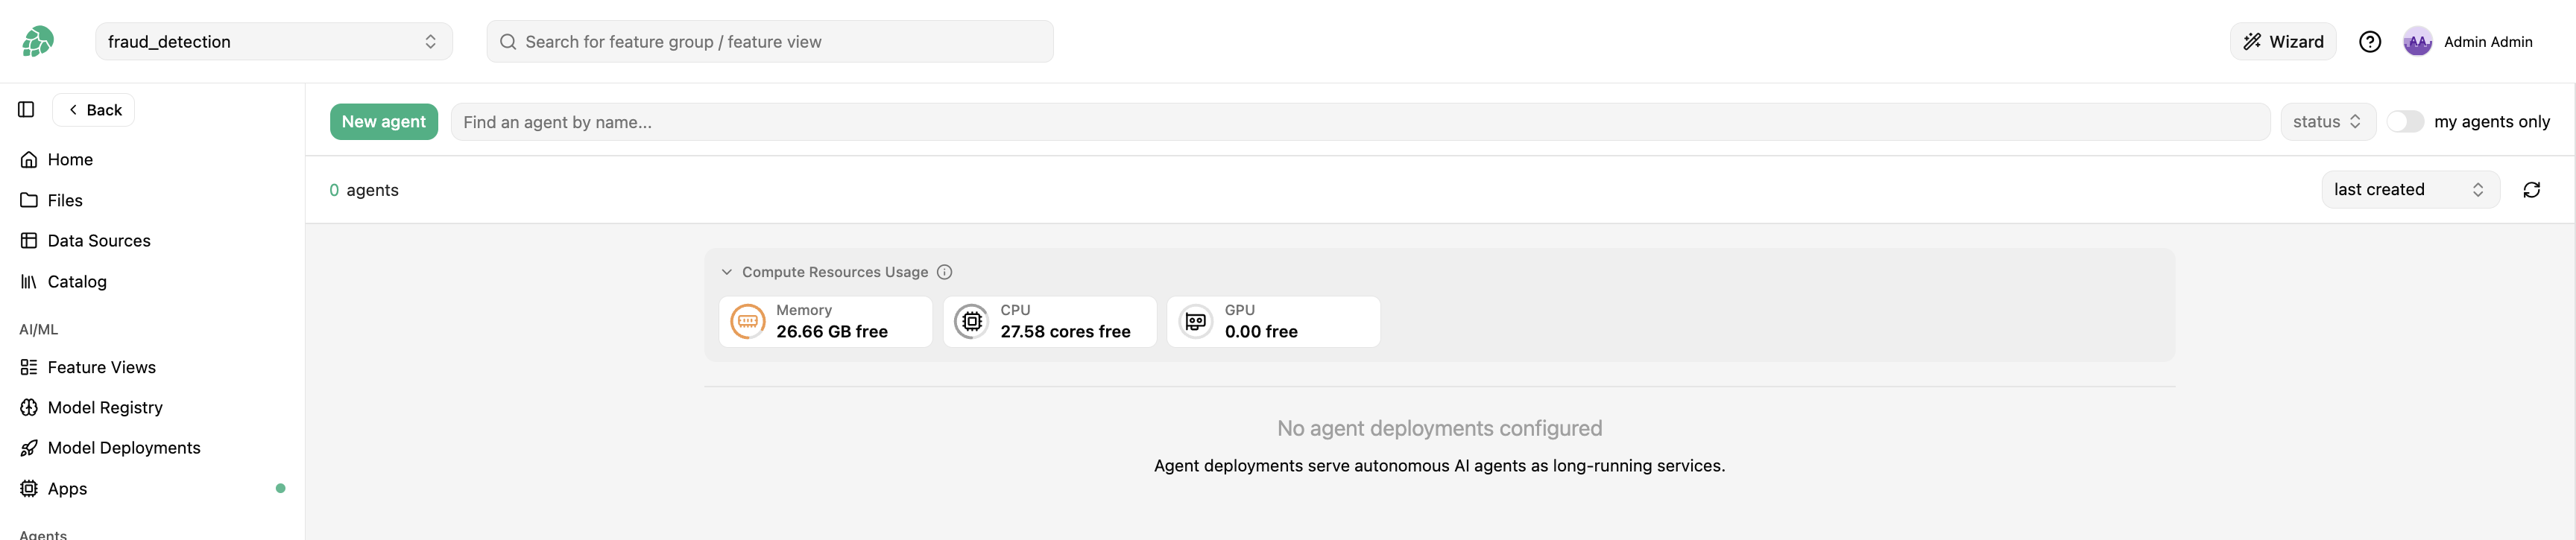
A Python deployment and an agent deployment are the same thing: a Python script served as a long-running service without a model artifact. Whether the script is a plain HTTP server or an autonomous agent, it is created and managed the same way. In the current UI both are listed under Agent Deployments and created from the same form.
Step 1: Create a new deployment#
Navigate to Agent Deployments under the Agents section of the navigation menu on the left, then click on New agent.
Step 2: Configure the deployment#
Choose a name for your deployment. Under Source, keep Project file to run a script already in the project, or select Git repository to clone the script on every start. Then provide the script under Agent script file by clicking on From project, Upload new file or Create new file.
Step 3 (Optional): Change Python environment#
The script runs in one of the Python Environments available in your project. This environment must have all the necessary dependencies for your Python program.
Select an environment from the Python Environment dropdown. Hopsworks provides built-in environments such as python-agent-pipeline and the *-inference-pipeline environments, each with a different set of libraries pre-installed.
To create your own environment it is recommended to clone the minimal-inference-pipeline or pandas-inference-pipeline environment and install additional dependencies needed for your Python program.

Step 4 (Optional): Advanced configuration#
Click on advanced options to configure the deployment further, including:
Once you are done with the changes, click on Create at the bottom of the form to create the deployment.
Code#
Step 1: Connect to Hopsworks#
Step 2: Implement a Python script#
Jupyter magic
In a jupyter notebook, you can add %%writefile python_server.py at the top of the cell to save it as a local file.
Step 3: Upload the script to your project#
Step 4: Create a deployment#
Step 5: Send requests#
Environment variables#
A number of different environment variables is available in the Python deployment to ease its implementation.
Available environment variables
These variables are available in all deployments.
| Name | Description |
|---|---|
DEPLOYMENT_NAME | Name of the current deployment |
DEPLOYMENT_VERSION | Version of the deployment |
ARTIFACT_FILES_PATH | Local path to the artifact files |
These variables are specific to Python deployments.
| Name | Description |
|---|---|
SCRIPT_PATH | Full path to the Python script |
SCRIPT_NAME | Prefixed filename of the Python script |
CONFIG_FILE_PATH | Local path to the configuration file (if provided) |
These variables are available in all deployments.
| Name | Description |
|---|---|
REST_ENDPOINT | Hopsworks REST API endpoint |
HOPSWORKS_PROJECT_ID | ID of the project |
HOPSWORKS_PROJECT_NAME | Name of the project |
HOPSWORKS_PUBLIC_HOST | Hopsworks public hostname |
API_KEY | API key for authenticating with Hopsworks services |
PROJECT_ID | Project ID (for Feature Store access) |
PROJECT_NAME | Project name (for Feature Store access) |
SECRETS_DIR | Path to secrets directory (/keys) |
MATERIAL_DIRECTORY | Path to TLS certificates (/certs) |
REQUESTS_VERIFY | SSL verification setting |
Python environments#
Python deployments run in one of the *-inference-pipeline Python environments available in your project. Hopsworks provides built-in environments like minimal-inference-pipeline, pandas-inference-pipeline or torch-inference-pipeline with different sets of libraries pre-installed. By default, the pandas-inference-pipeline environment is used.
To create your own environment, it is recommended to clone the minimal-inference-pipeline or pandas-inference-pipeline environment and install additional dependencies needed for your Python program. To learn more about Python environments, see Python Environments.
Resources#
Configure CPU, memory, and GPU allocation for your Python deployment. Each deployment component has separate request and limit values.
For full details on resource configuration, see the Resources Guide.
Autoscaling#
Deployments use Knative Pod Autoscaler (KPA) to automatically scale the number of replicas based on traffic. You can configure the minimum and maximum number of instances as well as the scale metric (requests per second or concurrency).
For full details on autoscaling parameters, see the Autoscaling Guide.
Scheduling#
Kueue is required
This feature requires Kueue to be enabled in your cluster. If Kueue is not available, queue and topology options will not be accessible.
If the cluster has Kueue enabled, you can select a queue for your deployment from the advanced configuration. Queues control resource allocation and scheduling priority across the cluster.
For full details on scheduling configuration, see the Scheduling Guide.